bare metal
The Full Performance of The Machine
Dedicated GPU clusters on NVIDIA Al factory reference architecture, with a full lifecycle control surface exposed via API. Integrated compute, storage, and networking. From thousands to tens of thousands of GPUs in a single cluster.
Available across NVIDIA Hopper, Blackwell Ultra, and Rubin-ready platforms.
Every operation, by API

Node Lifecycle
Provision, reboot, power-cycle, update, retire.

Health and Remediation
Cordon, reset, replace, return, restore. A failing node is isolated, remediated, and returned to the pool.

Configuration
Custom images, defined boot workflows, and pinned known-good firmware for reproducible node state across the fleet.

Automated provisioning, health monitoring, and node recovery let one team operate tens of thousands of GPUs. Failed nodes are detected and removed from scheduling without manual intervention.
One cluster, cleanly partitioned

Logically separated sub-clusters per team or tenant

Direct hardware access with no shared-host software

Single-tenant isolation or multi-tenant flexibility, your choice
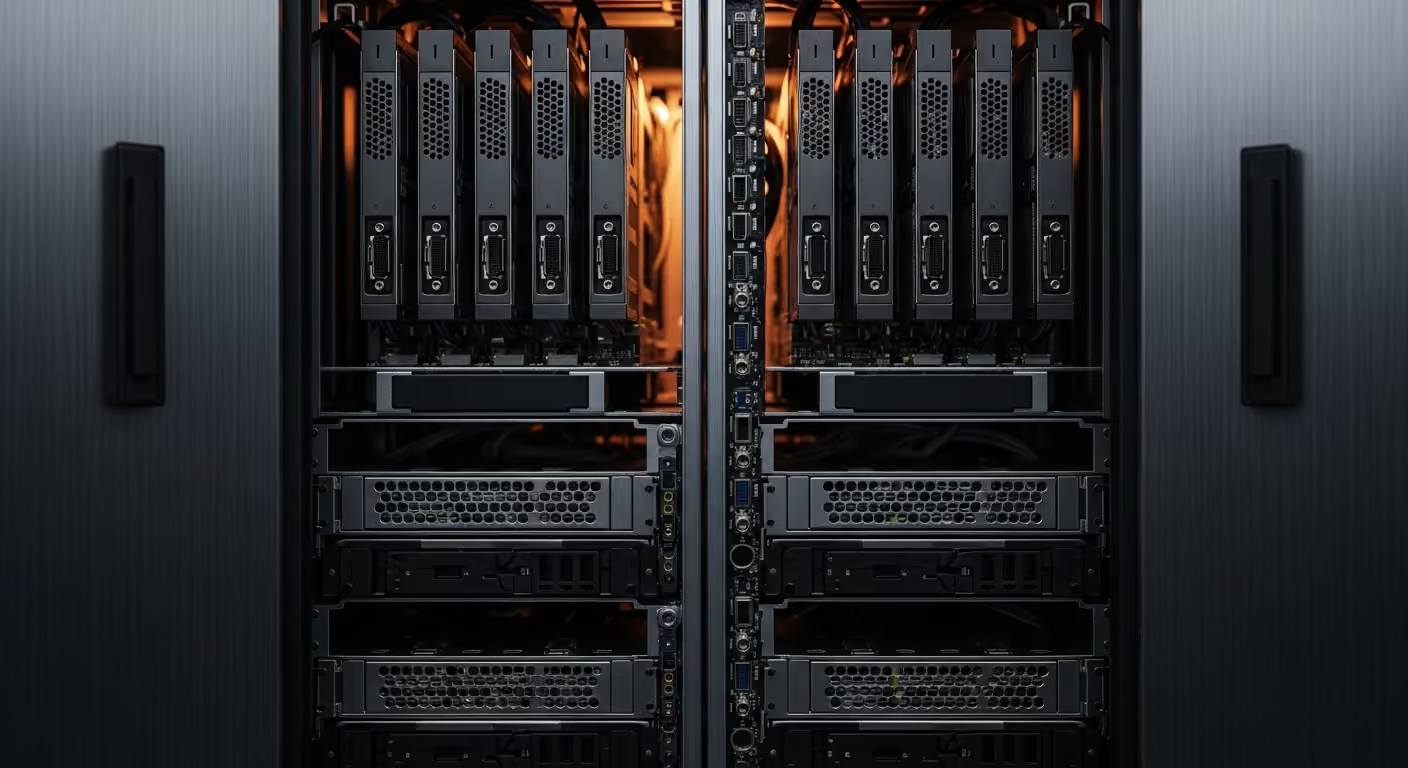
Compute, storage,
and networking
as one system
Compute, high-performance storage, and networking are engineered together to keep checkpoint writes and large-scale data movement fast.